I am amazed how often I see the very same piece of code used
by many different bloggers, often with very little thought as to the quality of
the code or the audience it’s going to. We all want to get the most out of free
code and avoid the pitfalls, so here’s some things to consider for bloggers and
users alike. Full article http://www.piper-rx.com/pages/tips/think_global.pdf
Tuesday, July 23, 2013


Tuesday, May 15, 2012
Health tip #3 – Avoid having too many concurrent managers
Here we go again! After having written and blogged about
this topic a fair bit in the past, having too many managers is a problem I
still continue to see all too often. A good example is a site I worked with
recently; it had 20+ managers just to run the workflow background processes.
Putting aside the need to address the excessive workflow background processes
(which is another problem in its own right) there are major issues with the
concurrent managers:
Problem #1 – Allowing 20 workflow background processes to
run at once competes for the same resources on the same tables.
Problem #2 – Is one of basic queuing theory –i.e. 20
processes all competing for the same CPU and data resources.
In theory, 1 CPU handles 2 concurrent processes so in this
case unless the site has 10 CPUs it runs the risk of CPU bottlenecking
problems. The sting in the tail is these problems become most evident when you
least need them to, like at high processing times such as month end.
What to do? It’s a simple choice. In this case identify why
you think you need so many concurrent managers. You need to fix the cause and
cut down on the number of managers, not just focus on the symptoms.
Want to know more? Take a look at the paper Concurrent Manager 101 & 202 on the www.piper-rx.com website. In fact there is heaps of FREE information
and tips on all aspects of OEBS Applications Administration at PIPER-Rx.com so
why not check it out!
Tuesday, March 13, 2012
Concurrent Managers Health Tip #2 – Scheduled Request Issues.
Scheduled requests are one of the mainstays of OEBS
concurrent processing.
One of the benefits of recurring scheduled requests is they
are “set and forget” they just happily run and resubmit without you having to
do a thing.
The biggest issue I’ve found, and this applies to almost all
sites, is the “forget” component. I regularly find scheduled requests that have
been running for years that are no longer required, and also duplicate
scheduled requests which have come about because someone doesn’t know the
original request exists. Both these issues are a waste of processing resources.
Another issue with scheduled requests is that I often find
resource intensive requests originally set to run overnight now creeping into
the working day because the request is resubmitting from the END of the prior
run.
You should periodically review your scheduled requests to
help avoid these issues.
Want to know more?
Download the simple OEBS scheduled requests report ordered
by program - TOAD Reports format report.
Report ID - PRXCMS-002
Using this report you should be able to identify both your
duplicates and those requests with a resubmit of END. By multiplying the “Re-submit”
value by the “Resub Count” you can get some idea how long the request has been
resubmitting.
Refer to PAM tutorial 19 “When Scheduled Requests Go Wrong”
Friday, February 3, 2012
Concurrent Managers Health Tip #1 – Rebuild your indexes!
This is really a simple one and you would be surprised how many
companies large and small overlook this.
I have seen examples of sites with over 50 million rows in
the fnd_concurrent_requests_u1 indexes; a huge
waste of space! More importantly however is the problem of poor performance in
such a core OEBS activity e.g. 10 concurrent manager processes running with a
30 second sleep time equates to 28,800 hits on your fnd_concurrent_requests
table and its indexes (this does not include your users submitting requests and
checking if their requests have completed). Get the picture why this is so
important.
As part of regular maintenance practices you should rebuild
your indexes on routinely purged objects on a regular basis, especially the
indexes on fnd_concurrent_requests.
Want to know if you need to rebuild your indexes? The
following article includes everything you need to know together with code and
there is also a TOAD report. These can be found on the PIPER-Rx “tips” page: http://www.piper-rx.com/pages/tips.html
Rebuilding indexes
in an OEBS environment - A guide to rebuilding indexes in an OEBS
environment
View and Download associated TOAD report (TRD format) - Report id - FDBA002-10
Also remember some OEBS application monitors provide alerting to remind you when your indexes may need maintenance.
Happy Rebuilding J
Friday, December 9, 2011
Improving the business efficiency of OEBS workflow. Part 2: Validating e-mail addresses
This paper is the second of a two (2) part
series. Part 2 covers e-mail address validation using a 12 point PLSQL e-mail
addresses validation function.
Using the PLSQL function we cover e-mail
validation of addresses in both the wf_local_roles and wf_local_users objects
and in a number of base application objects that populate the workflow roles
and users objects.
The paper and the PLSQL function can be viewed or downloaded at the following addresses
PDF document, 500 Kb
http://www.piper-rx.com/pages/papers/email_validation_part_two.pdf
PLSQL, 8 Kb
http://www.piper-rx.com/pages/papers/piper_rx_email_validation.sql
-Gary
Sunday, November 20, 2011
Improving the business efficiency of OEBS workflow. Part 1: Missing e-mail addresses
This paper is part one (1) of a two (2)
part series. Part 1 covers null e-mail addresses in your workflow roles objects
and in part 2 we covers e-mail address validation including a free 12 point PLSQL function
for validating e-mail addresses.
In this paper we cover the issue of missing
(null) workflow e-mail addresses:
v The importance of a SYSADMIN e-mail address
The paper can be viewed or downloaded at the following address:
Part 1: Missing e-mail addresses
PDF document, 300 Kb
In part 2 of the “Improving the business efficiency of OEBS workflow” series we will cover email address validation. Part 2 also includes an 12 point email address validation function.
v What happens when an invalid
e-mail address is encountered?
v Assessing the damage in your instance ( Free SQL )
v And how to rectify the issue
The paper can be viewed or downloaded at the following address:
Part 1: Missing e-mail addresses
PDF document, 300 Kb
In part 2 of the “Improving the business efficiency of OEBS workflow” series we will cover email address validation. Part 2 also includes an 12 point email address validation function.
-Gary
Monday, February 28, 2011
Did you know you can change an apps user’s account name?
First and foremost this is done via the normal apps Security > User > Define screen.
Whilst the account name (user_name) has to be unique which is enforced by the fnd_user_u2 index, the internal application key is based on the account ID (user_id) not the name
So why would you change an account name?
Of course you will need to get this approach signed off by Oracle support and internal audit first. Usually, as long as there is consistent documented evidence of the change audit are generally ok
You are not doing anything dodgy here, this is all done via the standard Oracle application screens (Security > User > Define) just select the user, change the users name and commit.
Note: If you change the name of an active account, you will need to reset that user's password and let them know the password you have set and that they will be required to change their password on first connecting with the new name.
Of course you wouldn’t even attempt to do this without checking with Oracle support and you’re your audit team before changing application user names and then testing, testing etc…..
Whilst the account name (user_name) has to be unique which is enforced by the fnd_user_u2 index, the internal application key is based on the account ID (user_id) not the name
So why would you change an account name?
- A name change by deed poll or marriage
- A new employee has the same name as an ex-employee
- The user name was entered incorrectly
- You want to implement a user naming standard
Of course you will need to get this approach signed off by Oracle support and internal audit first. Usually, as long as there is consistent documented evidence of the change audit are generally ok
You are not doing anything dodgy here, this is all done via the standard Oracle application screens (Security > User > Define) just select the user, change the users name and commit.
Note: If you change the name of an active account, you will need to reset that user's password and let them know the password you have set and that they will be required to change their password on first connecting with the new name.
Of course you wouldn’t even attempt to do this without checking with Oracle support and you’re your audit team before changing application user names and then testing, testing etc…..
Saturday, January 15, 2011
Rebuilding indexes in an OEBS environment
Index maintenance is all too often overlooked and can, over time, have a serious impact on performance. Ever growing indexes account for large amounts of wasted space and failing to perform regular index rebuilds on dynamic application tables is just throwing away performance.
When APPLSYS has over a thousand indexes the OEBS application has over 60,000 indexes (version and module dependant) it often gets too hard to identify what indexes require rebuilding and they simply don’t get rebuilt. Believe it or not, most sites I visit have not rebuilt indexes on even the basic regularly purged objects such as concurrent requests and sign-on audit tables in years.
Example:
A site I recently reviewed generates approximately 35,900 fnd_concurrent _requests records per day which are being purged nightly holding 7 days history on-line. The indexes had not been rebuilt for over 4 years. Thus in this instance the base table should be holding approximately 251,000 records whereas the primary key index fnd_concurrent_requests_u1 would be holding approximately 52 million rows. 99.9% deleted rows. This is an interesting one when you calculate the space the index is holding, I estimate over 1.4 Gb for fnd_concurrent_requests_u1 alone.
In this paper we will provide a simple list of indexes to start with, and a method of identifying if any of these indexes should be rebuilt.
We also cover why you should exercise caution when using an auto index rebuild script you find on the web, some do not readily translate to an OEBS environment
The full paper can be found at http://www.piper-rx.com/pages/tips.html - Look for "Rebuilding indexes in an OEBS environment" in the tips section
Friday, December 17, 2010
Aged User Accounts
Much like the Accounts Receivable ages debtor accounts function in any business, we can age application user accounts that have never connected to the application or have not connected in some time via the full and self-service screens.
Why would we want to do this? Having people who have long left the business retaining active accounts is a security issue, and all the best managed sites have processes in place to check that such accounts are being closed on a timely basis.
It is possible to generate a list of application user accounts that have either never connected or have not connected in the last 120 days.
The first step is to identify the number of accounts you have that are candidates for review:
SELECT count(*)
FROM applsys.fnd_user fu
WHERE (fu.last_logon_date is null
or (sysdate - fu.last_logon_date) >= 120 )
and (fu.end_date is null
or fu.end_date > sysdate )
and fu.user_name not in ('SYSADMIN','GUEST');
The second step is to produce a list of application accounts that are candidates for review:
SELECT fu.user_id,
fu.user_name,
substr(fu.description, 1, 40)
decode(sign(length(fu.description) - 40), 1, '...') description,
nvl(to_char(fu.last_logon_date, 'DD-Mon-YY HH24:MI'), 'Never Connected')
last_connect_date,
decode(fu.last_logon_date, null, null,
round( (sysdate - fu.last_logon_date),0) ) days_since_last_connect
FROM applsys.fnd_user fu
WHERE (fu.last_logon_date is null
or (sysdate - fu.last_logon_date) >= 120 )
and (fu.end_date is null
or fu.end_date > sysdate )
and fu.user_name not in ('SYSADMIN','GUEST')
ORDER by decode(fu.last_logon_date, null, (sysdate - 10000), fu.last_logon_date),
fu.user_name;
The output will look something like the following example:
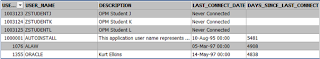
Remember: Not all Aged User Accounts are candidates for end dating:
There are of course exceptions, those accounts that must exist but are never used and those that are used very infrequently. You can exclude these by simply adding these accounts to your SQL statement:
and fu.user_name not in (‘SYSADMIN’,’GUEST’)
You should run the second report say once per month as part of your normal application maintenance routine and send it to your HR department or whoever manages your application user accounts. It shows the business you are on top of managing the application and the business loves anything to do with security...
Why would we want to do this? Having people who have long left the business retaining active accounts is a security issue, and all the best managed sites have processes in place to check that such accounts are being closed on a timely basis.
It is possible to generate a list of application user accounts that have either never connected or have not connected in the last 120 days.
The first step is to identify the number of accounts you have that are candidates for review:
SELECT count(*)
FROM applsys.fnd_user fu
WHERE (fu.last_logon_date is null
or (sysdate - fu.last_logon_date) >= 120 )
and (fu.end_date is null
or fu.end_date > sysdate )
and fu.user_name not in ('SYSADMIN','GUEST');
The second step is to produce a list of application accounts that are candidates for review:
SELECT fu.user_id,
fu.user_name,
substr(fu.description, 1, 40)
decode(sign(length(fu.description) - 40), 1, '...') description,
nvl(to_char(fu.last_logon_date, 'DD-Mon-YY HH24:MI'), 'Never Connected')
last_connect_date,
decode(fu.last_logon_date, null, null,
round( (sysdate - fu.last_logon_date),0) ) days_since_last_connect
FROM applsys.fnd_user fu
WHERE (fu.last_logon_date is null
or (sysdate - fu.last_logon_date) >= 120 )
and (fu.end_date is null
or fu.end_date > sysdate )
and fu.user_name not in ('SYSADMIN','GUEST')
ORDER by decode(fu.last_logon_date, null, (sysdate - 10000), fu.last_logon_date),
fu.user_name;
The output will look something like the following example:

Remember: Not all Aged User Accounts are candidates for end dating:
There are of course exceptions, those accounts that must exist but are never used and those that are used very infrequently. You can exclude these by simply adding these accounts to your SQL statement:
and fu.user_name not in (‘SYSADMIN’,’GUEST’)
You should run the second report say once per month as part of your normal application maintenance routine and send it to your HR department or whoever manages your application user accounts. It shows the business you are on top of managing the application and the business loves anything to do with security...
Friday, November 19, 2010
Is the number of concurrent manager processes you have causing performance issues?
All too often I see sites with far too many concurrent manager processes and the site wonders why they have intermittent performance issues. Remember, having more concurrent manager processes does not mean more throughput.
So, how many concurrent manager processes should you have?
Add up the number of standard and custom concurrent manager processes you have. If that value exceeds 2 times the number of CPUs (multi core adjusted) on the box you most likely have too many manager processes. If you are experiencing intermittent performance issues, particularly around high processing times like financial month ends, too many manager processes would most likely be one of your reasons.
The following SQL will list your concurrent managers:
SELECT concurrent_queue_name,
max_processes,
running_processes,
nvl(sleep_seconds,0) sleep_seconds,
cache_size,
decode(enabled_flag,
'Y', 'Enabled', 'N', 'Disabled', 'Unknown' ) status
FROM applsys.fnd_concurrent_queues
ORDER by decode(enabled_flag, 'Y', 1, 'N', 0, enabled_flag ) DESC,
max_processes DESC,
decode(concurrent_queue_name,
'FNDICM', 'AA',
'FNDCRM', 'AB',
'STANDARD', 'AC',
concurrent_queue_name);

A real world example of too many managers:
A site I reviewed had 54 standard manager processes on a 4 CPU box - 54 / 4 = 13.5
In this example there can be up to 54 concurrent requests running through the standard managers at any time which will just plain flood the CPUs. Generally running two (2) concurrent requests per CPU is sufficient to leave enough overhead for normal processing activities; any more than that and the risk increases of CPU flooding. And you would hope this site does run too many FSG’s... as we all know the damage they can do...
Believe it or not I have even seen 108 standard managers on an 8 CPU box..... Hmmm.....
Flooding the CPUs with concurrent requests leaves very little available CPU for normal user requests. As a result users tend to experience poor performance with their forms etc... It’s basic queuing theory... To make matters worse, these intermittent performance issues tend to occur around peak processing times when the concurrent manager load is at its peak; exactly the time users are clearly very busy and don’t want to be experiencing performance issues.
If you have a “problem” with an excessive number of standard and custom concurrent managers processes, what you need to do is lower the number of processes. This is easier said than done, as once they exist the business is very reluctant to let them go. But it is worth persisting as it will make a difference!
For more information refer to the paper I wrote:
http://www.piper-rx.com/pages/papers/cm101.pdf
Believe it or not, and much to my surprise, this is the most down loaded paper on my web site. Even though I wrote this paper in 2004, it still holds true today.... not much changes in OEBS, and for good reason; stability in accounting and business systems is what businesses want.
So, how many concurrent manager processes should you have?
Add up the number of standard and custom concurrent manager processes you have. If that value exceeds 2 times the number of CPUs (multi core adjusted) on the box you most likely have too many manager processes. If you are experiencing intermittent performance issues, particularly around high processing times like financial month ends, too many manager processes would most likely be one of your reasons.
The following SQL will list your concurrent managers:
SELECT concurrent_queue_name,
max_processes,
running_processes,
nvl(sleep_seconds,0) sleep_seconds,
cache_size,
decode(enabled_flag,
'Y', 'Enabled', 'N', 'Disabled', 'Unknown' ) status
FROM applsys.fnd_concurrent_queues
ORDER by decode(enabled_flag, 'Y', 1, 'N', 0, enabled_flag ) DESC,
max_processes DESC,
decode(concurrent_queue_name,
'FNDICM', 'AA',
'FNDCRM', 'AB',
'STANDARD', 'AC',
concurrent_queue_name);
Example Output

A real world example of too many managers:
A site I reviewed had 54 standard manager processes on a 4 CPU box - 54 / 4 = 13.5
In this example there can be up to 54 concurrent requests running through the standard managers at any time which will just plain flood the CPUs. Generally running two (2) concurrent requests per CPU is sufficient to leave enough overhead for normal processing activities; any more than that and the risk increases of CPU flooding. And you would hope this site does run too many FSG’s... as we all know the damage they can do...
Believe it or not I have even seen 108 standard managers on an 8 CPU box..... Hmmm.....
Flooding the CPUs with concurrent requests leaves very little available CPU for normal user requests. As a result users tend to experience poor performance with their forms etc... It’s basic queuing theory... To make matters worse, these intermittent performance issues tend to occur around peak processing times when the concurrent manager load is at its peak; exactly the time users are clearly very busy and don’t want to be experiencing performance issues.
If you have a “problem” with an excessive number of standard and custom concurrent managers processes, what you need to do is lower the number of processes. This is easier said than done, as once they exist the business is very reluctant to let them go. But it is worth persisting as it will make a difference!
For more information refer to the paper I wrote:
http://www.piper-rx.com/pages/papers/cm101.pdf
Believe it or not, and much to my surprise, this is the most down loaded paper on my web site. Even though I wrote this paper in 2004, it still holds true today.... not much changes in OEBS, and for good reason; stability in accounting and business systems is what businesses want.
Saturday, November 6, 2010
Case Review - How did I manage to get 30 million rows in my fnd_logins table?
The site in presented with over 30 million rows in the fnd_logins table, growing at a rate of approximately 25,000 records per day.
Based on the site’s application activity, the estimated number of rows that should be held in the fnd_logins table should be around 800,000 records (i.e. holding 32 days history on-line). It is expected that this number should reduce post concurrent manager activity review.
The site was running the concurrent program Purge Signon Audit data (FNDSCPRG) daily as part of their normal maintenance program to purge the sign-on audit data and was unaware of the high growth rate in the sign-on audit tables.
On review of the site’s scheduled requests it was found that the Purge Signon Audit data was being run daily with the date argument set to 10-Oct-06, however, “the increment date parameter each run” check box had not been checked when the scheduled request was created. As such the data parameter has not been incrementing with each run, thus with each run the program has been purging all sign-on audit records prior to 10-Oct-06. As a result any record added after that date has not been being purged.
So, since 10-Oct-06 (Over 1,200 days at the time of presentation) the program has been running but purging nothing.
Whilst there are several inherent performance issues, the biggest impact to the application would be when the concurrent program runs. The concurrent program Purge Signon Audit data (FNDSCPRG) uses an un-indexed column start_time in its execution. As such the purge program will execute a full scan on each of the target tables in order to determine the rows to delete. So for this site, that would include a daily full scan of a 30 million to not find any rows to delete.
The case review shows how I would “Fix” the issue including deleting the unwanted rows and setting up a new Purge Signon Audit data scheduled program run.
The full case review can be found at -
http://www.piper-rx.com/pages/case_reviews/case_sign_on_audit.pdf
Sunday, October 10, 2010
Better Date and Elapsed Time Reporting Formats for Business Users
I am a business user, so why say to me “it ran for 0.049 days”?
All too often I see reports created by technical staff and DBAs being presented to management and business users with elapsed times (such as concurrent request run times) calculated in days or seconds and this often causes frustration amongst report recipients. Here are some typical examples:-
• A concurrent request run time of 1 hour and 10 minutes is commonly reported as:
What you should remember when dealing with management or users is they usually hate having to perform mental gymnastics to calculate a time, what is 0.02 days or 1,454 seconds?
Would it not be better if the time was quoted as 28 minutes? I believe it’s always preferable when presenting information to management and business users to convert elapsed time to Days, Hours and Minutes.
The following is an example report showing both YY:MM:DD and DD:HH:MI formats:

Remember; always make life easier for your target user. They will appreciate it and in turn will be more likely to be supportive when you need it!
All too often I see reports created by technical staff and DBAs being presented to management and business users with elapsed times (such as concurrent request run times) calculated in days or seconds and this often causes frustration amongst report recipients. Here are some typical examples:-
• A concurrent request run time of 1 hour and 10 minutes is commonly reported as:
- 0.0486 days or
- 4,200 seconds
What you should remember when dealing with management or users is they usually hate having to perform mental gymnastics to calculate a time, what is 0.02 days or 1,454 seconds?
Would it not be better if the time was quoted as 28 minutes? I believe it’s always preferable when presenting information to management and business users to convert elapsed time to Days, Hours and Minutes.
The following is an example report showing both YY:MM:DD and DD:HH:MI formats:

The full article including example SQL can be found at:
http://www.piper-rx.com/pages/tips/date_time_formatting.pdf Remember; always make life easier for your target user. They will appreciate it and in turn will be more likely to be supportive when you need it!
Tuesday, September 21, 2010
A workflow Case Review on how to lower the number of Workflow Background Processes
Having encountered a number of sites running upward of over 5,000 workflow background processes per day, in some cases over 15,000 per day, it never ceases to amaze me how so many sites get themselves into so much trouble running far too many background processes. Not only does this thrash your application but it also has an impact on your concurrent request tables as each request adds a record in the fnd_concurrent_requests table for each run.
Just recently I have been corresponding with a site that contacted me regarding issues with their workflow application and this has prompted me to put together a case review to articulate how I would look to resolve the issue of too many workflow background processes for the particular scenario outlined.
The full case review can be found on my web site:
http://www.piper-rx.com/pages/case_reviews/case_wf_bgp.pdf
It’s pointless looking for poor performing code with this issue…
-Gary
Just recently I have been corresponding with a site that contacted me regarding issues with their workflow application and this has prompted me to put together a case review to articulate how I would look to resolve the issue of too many workflow background processes for the particular scenario outlined.
The full case review can be found on my web site:
http://www.piper-rx.com/pages/case_reviews/case_wf_bgp.pdf
It’s pointless looking for poor performing code with this issue…
This is a good example of my statement “Not all performance issues are solved by code tuning”.
-Gary
Monday, September 13, 2010
Shortening large columns in user facing reports
Where a database column and its content is larger than the size you wish to show in a report, it is easy to just substring the column value to fit your report column size. However, this often does not look that good in user facing reports.
To demonstrate this concept below I have used the application users description column in applsys.fnd_user which is a varchar2(240)...
SELECT fu.user_id user_id,
fu.user_name user_name,
fu.description description
FROM applsys.fnd_user fu;

In most cases when you write a report you substring the column to the size of the column in your report. Whilst sub stringing the column value is the easy solution and in your mind acceptable, you should remember your reports are aimed at end users wouldn’t it look more professional if you added three (3) full stops to a sub stringed value to clearly indicate the column has been truncated.
SELECT fu.user_id user_id,
fu.user_name user_name,
substr(fu.description, 1, 30)
decode(sign(length(fu.description) - 30), 1, '...') description
FROM applsys.fnd_user fu;

If your report column size is 30, set the two (2) values in the example SQL to 27, that is 27 characters plus 3 for the full stops.
A very simple piece of code but what a difference. You should consider using this for any user report where a data column that has been truncated.
Remember:
“Always make life easier for your target user”
- Gary
Saturday, August 28, 2010
General Ledger - GL Program Optimizer
The General Ledger - GL program optimizer is a concurrent program that is available to the GL super user responsibility and it has two functions:
The program collects and stores information on the spread of balances in gl.gl_balances which is used by both the GL posting program and FSGs. Given that the number of balances in gl.gl_balances increases each month with the month end roll process, it is important for the overall performance of posting and FSGs to keep the GL program optimizer stats up to date.
When was the GL Program Optimizer last run?
The following SQL shows you when the GL program optimizer was last run and by whom:
SELECT fu.user_name || ' - ' ||fu.description "Last Run By",
to_char(max(rts.last_update_date),'DD-Mon-YY HH24:MI') "Last Run",
trunc(sysdate - max(rts.last_update_date)) "Age (Days)"
FROM rg.rg_table_sizes rts,
applsys.fnd_user fu
WHERE rts.last_updated_by = fu.user_id
GROUP by fu.user_name, fu.description;
It is not uncommon for the program to have never been run.
Warning: Do not set the Rebuild Indexes option to Yes as this could cause more damage and may have an adverse effect on the entire General Ledger application. FYI Older releases dropped existing code combination indexes and rebuild indexes as defined in the flexfield definitions. Current releases will maintain existing indexes and build only those that have been defined in the flexfiled definitions that do not currently exist.
Given the above warning, what we don’t want is any of the GL super users finding the GL program optimizer program and running it thinking they are doing the right thing; I have been there and it’s not pretty. That’s why I always remove it from the GL super user responsibility and add it to the Systems Administrator responsibility which they cannot get to.
- Collect statistics to aid in the running of FSGs and posting
- Build indexes on gl_code_conbinations where they do not exist.
The program collects and stores information on the spread of balances in gl.gl_balances which is used by both the GL posting program and FSGs. Given that the number of balances in gl.gl_balances increases each month with the month end roll process, it is important for the overall performance of posting and FSGs to keep the GL program optimizer stats up to date.
When was the GL Program Optimizer last run?
The following SQL shows you when the GL program optimizer was last run and by whom:
SELECT fu.user_name || ' - ' ||fu.description "Last Run By",
to_char(max(rts.last_update_date),'DD-Mon-YY HH24:MI') "Last Run",
trunc(sysdate - max(rts.last_update_date)) "Age (Days)"
FROM rg.rg_table_sizes rts,
applsys.fnd_user fu
WHERE rts.last_updated_by = fu.user_id
GROUP by fu.user_name, fu.description;
It is not uncommon for the program to have never been run.
This program is run by logging onto the GL super user responsibility and then running the concurrent program - GL Program Optimizer.
When running the GL Program Optimizer there are two options:
- Collect Statistics (Default Yes) -Set this value to Yes
- Rebuild Indexes (Default No) - Set this value to No
Warning: Do not set the Rebuild Indexes option to Yes as this could cause more damage and may have an adverse effect on the entire General Ledger application. FYI Older releases dropped existing code combination indexes and rebuild indexes as defined in the flexfield definitions. Current releases will maintain existing indexes and build only those that have been defined in the flexfiled definitions that do not currently exist.
Given the above warning, what we don’t want is any of the GL super users finding the GL program optimizer program and running it thinking they are doing the right thing; I have been there and it’s not pretty. That’s why I always remove it from the GL super user responsibility and add it to the Systems Administrator responsibility which they cannot get to.
How often should GL Program Optimizer be run?
I generally set this up as a scheduled job to be run once per month, a couple of days after the month end roll over.
Good Luck....
Friday, August 13, 2010
What OEBS Application modules are installed?
The following genreates a list of the OEBS Application modules you have installed including their version and patch levels...
SELECT fa.application_id appn_id,
decode(fa.application_short_name,
'SQLAP', 'AP', 'SQLGL', 'GL', fa.application_short_name ) appn_short_name,
substr(fat.application_name,1,50)
decode(sign(length(fat.application_name) - 50), 1, '...') Application,
fa.basepath Base_path,
fl.meaning install_status,
nvl(fpi.product_version, 'Not Available') product_version,
nvl(fpi.patch_level, 'Not Available') patch_level,
to_char(fa.last_update_date, 'DD-Mon-YY (Dy) HH24:MI') last_update_date,
nvl(fu.user_name, '* Install *') Updated_by
FROM applsys.fnd_application fa,
applsys.fnd_application_tl fat,
applsys.fnd_user fu,
applsys.fnd_product_installations fpi,
apps.fnd_lookups fl
WHERE fa.application_id = fat.application_id
and fat.language(+) = userenv('LANG')
and fa.application_id = fpi.application_id
and fpi.last_updated_by = fu.user_id(+)
and fpi.status = fl.lookup_code
and fl.lookup_type = 'FND_PRODUCT_STATUS'
UNION ALL
SELECT fa.application_id,
fa.application_short_name,
substr(fat.application_name,1,50)
decode(sign(length(fat.application_name) - 50), 1, '...'),
fa.basepath,
'Not Available',
'Not Available',
'Not Available',
to_char(fa.last_update_date, 'DD-Mon-YY (Dy) HH24:MI'),
nvl(fu.user_name, '* Install *')
FROM applsys.fnd_application fa,
applsys.fnd_application_tl fat,
applsys.fnd_user fu
WHERE fa.application_id = fat.application_id
and fat.language(+) = userenv('LANG')
and fa.last_updated_by = fu.user_id(+)
and fa.application_id not in
( SELECT fpi.application_id
FROM applsys.fnd_product_installations fpi )
ORDER by 2;
Example output:

Note: For readability I have converted the SQLAP to AP and SQLGL to GL – this looks so much better for users...
Hope this is useful....
Subscribe to:
Posts (Atom)